Unique ID Generators
When multiple application servers write records concurrently, a single database auto-increment sequence becomes a shared bottleneck. Every insert must ask one central node for the next integer, adding a network round trip and creating a single point of failure. Distributed unique ID generators solve this by producing globally unique identifiers locally on each server without runtime coordination.
Why Auto-Increment Does Not Scale Horizontally
A single-node relational database assigns sequential integers (1, 2, 3, ...) safely because one process holds a lock on the counter. Spreading writes across many servers forces a choice between two problems: keeping one central counter that limits throughput, or running independent counters on each server that collide on the same IDs.
A distributed ID generator for write-heavy services typically targets four properties:
- Global uniqueness: No two servers emit the same ID, even when generating at the same millisecond.
- No runtime coordination: Each node produces IDs in local memory in sub-millisecond time and keeps working when peer nodes fail.
- Compact size: Smaller IDs (such as 64-bit integers) use less RAM and disk in primary and secondary indexes.
- Time sortability: Newer IDs sort greater than older IDs, which supports chronological feeds and keeps database index writes sequential.
Snowflake IDs
Snowflake, originally designed at Twitter, encodes uniqueness directly into the bit layout of a 64-bit signed integer. Because every server receives a distinct machine ID at startup and embeds the current timestamp in the most-significant bits, servers generate unique, roughly time-ordered IDs with zero runtime communication.
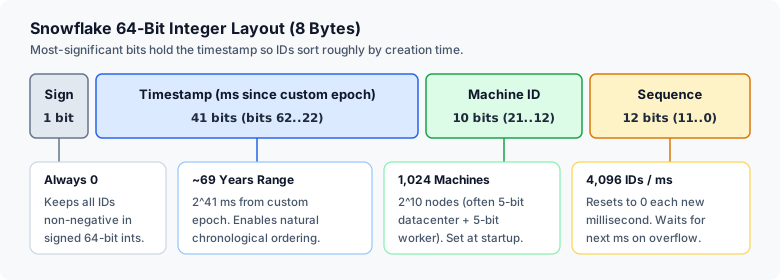

The 64 bits split into four fixed fields:
- Sign bit (1 bit): Always
0, keeping every generated value non-negative in signed 64-bit database integer columns. - Timestamp (41 bits): Milliseconds elapsed since a chosen custom epoch (for example,
2020-01-01). Forty-one bits cover from that epoch, and placing the timestamp first makes IDs sortable by creation time. - Machine ID (10 bits): A unique node identifier assigned at startup, supporting . Two servers generating IDs in the exact same millisecond produce different integers because their machine bits differ.
- Sequence number (12 bits): A per-machine counter that increments for multiple requests within the same millisecond and resets to
0when the clock advances. Twelve bits allow on each server.
To see how these fields interact, consider three servers starting at timestamp offset 63,158,400,000 ms (2022-01-01). Server 1 (machine_id = 1) emits its first ID with sequence = 0. A second request arriving on Server 1 in the same millisecond increments sequence to 1. Server 2 (machine_id = 2) emits an ID in that same millisecond with sequence = 0, and its machine bits guarantee a distinct 64-bit integer. If Server 1 hits sequence = 4,095 in a single millisecond, it pauses until the next millisecond tick and resets sequence to 0.
Click + Generate ID on Server 1 twice to watch the 12-bit sequence increment in the same millisecond, then switch to Server 2 (ID 2) and click + Generate ID, and finally click ⚡ Trigger Seq Overflow to see the generator roll over to the next millisecond.
Snowflake Implementation
The code below builds and decodes 64-bit Snowflake IDs across three simulated servers, using a lock to protect the per-machine sequence counter and waiting for the next millisecond on overflow.
Snowflake ID Generator
Interactive implementation showing distributed unique ID generation across multiple servers
Operational Limits: Clock Skew and Setup Coordination
Snowflake avoids runtime coordination, so its operational risks sit in two places:
- Clock drift and backward jumps: If NTP adjusts a server's system clock backward, the generator could reuse a timestamp and sequence pair already emitted earlier. Production generators compare
timestampagainstlast_timestamp: for a small backward step (a few milliseconds), the node waits until the clock catches up; for a larger jump, the node refuses to issue IDs and alerts operators. - Startup machine ID assignment: Two nodes sharing the same 10-bit machine ID will collide if they emit IDs in the same millisecond. Deployments assign unique machine IDs during startup through a coordination service (such as ZooKeeper or etcd), a startup lease table in a relational database, or deterministic container ordinals (such as Kubernetes StatefulSet pod indices).
- Exposed timestamps: Because the creation time sits in the top 41 bits, anyone reading an ID can decode when the record was created and estimate rough write volume.
Alternative ID Strategies
UUID v4 and B-Tree Write Amplification
A UUID v4 (Universally Unique Identifier, version 4) is a 128-bit value containing 122 random bits and 6 fixed version/variant bits, formatted as a 36-character hex string such as f47ac10b-58cc-4372-a567-0e02b2c3d479. Because randomness alone provides , any server or offline client can generate UUID v4 values with zero setup coordination and no clock dependency.
The cost is storage size and write performance on B-tree primary keys. Each UUID takes 16 bytes instead of 8 bytes (doubling primary-key size in every secondary index). More importantly, random keys scatter inserts across the entire B-tree instead of appending to the rightmost leaf page.
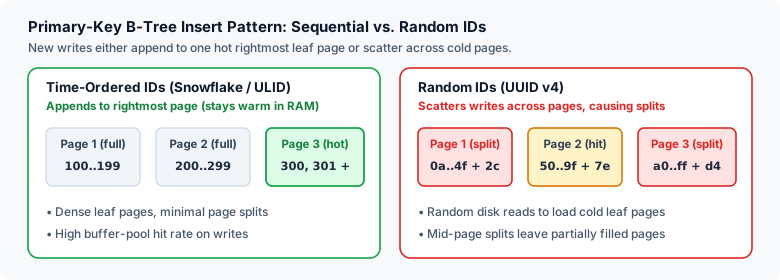
Random inserts force the database to read cold leaf pages from disk into the buffer pool and split full pages in the middle of the tree, leaving pages partially empty and degrading cache hit rates on write-heavy tables. UUID v7 (standardized in RFC 9562) addresses this by placing a 48-bit Unix millisecond timestamp in the leading bits, restoring sequential B-tree inserts while keeping the 128-bit UUID format.
ULID
A ULID (Universally Unique Lexicographically Sortable Identifier) is a 128-bit ID combining a 48-bit millisecond timestamp with 80 bits of randomness, encoded as a 26-character Crockford Base32 string such as 01F8VYXK67BGC1XPD2YH1W8HTH.
The 48-bit timestamp covers and makes ULIDs sortable both numerically and lexicographically as strings. Because the remaining 80 bits are random, ULIDs need no startup machine-ID registry and work across more than 1,024 nodes. The trade-off compared to Snowflake is size: 16 bytes binary (or 26 ASCII characters) versus 8 bytes.
Partitioned Auto-Increment
Partitioned auto-increment assigns each database node a distinct starting offset and a stride equal to the node count N. With three servers (N = 3), Server 1 generates 1, 4, 7, 10, Server 2 generates 2, 5, 8, 11, and Server 3 generates 3, 6, 9, 12.
This keeps 8-byte integer keys and uses native database sequences without cross-node locking. The limitation appears when scaling the cluster: adding a fourth server changes the stride from 3 to 4, which requires reconfiguring every node's increment and offset carefully to avoid overlapping previously issued integers. Moreover, if one node receives heavier traffic than another, IDs drift out of global time order.
Choosing an ID Strategy
| Property | Snowflake | UUID v4 | ULID / UUID v7 | Partitioned Auto-Increment |
|---|---|---|---|---|
| Size (binary) | 8 bytes (64-bit) | 16 bytes (128-bit) | 16 bytes (128-bit) | 8 bytes (64-bit) |
| Time-sortable | Yes | No | Yes | Only per node |
| Setup coordination | Machine ID registry | None | None | Fixed offset + stride |
| Runtime coordination | None | None | None | None (local DB) |
| Clock dependency | Yes | No | Yes | No |
| B-tree write locality | High (sequential) | Low (random splits) | High (sequential) | High (per node) |
| Predictable / leaks time | Yes | No | Yes | Leaks total volume |
Four constraints narrow the choice quickly:
- Write-heavy B-tree tables needing compact 8-byte keys: Choose Snowflake when the fleet fits within the machine-ID bit budget (for example, under 1,024 nodes) and startup ID assignment is already managed.
- No machine-ID coordination, over 1,024 nodes, or client-side generation with time sorting: Choose ULID or UUID v7.
- Unguessable IDs where leaking creation time is undesirable: Choose UUID v4 (or a random prefixed ID) and avoid using it as the clustered B-tree key on write-heavy tables if insert throughput is a bottleneck.
- Small fixed set of relational primaries: Partitioned auto-increment keeps native database sequences, provided the node count rarely changes.
Custom Prefixed IDs
Public APIs often decouple external identifiers from internal database keys so teams can migrate storage engines without changing URLs or exposing sequential counts.
- Prefixed random IDs (Stripe): Formats such as
cus_1234567890abcdef,ch_3L4E5Y2eZvKYlo2C, andinv_1GjJKl2eZvKYlo2Cprepend a resource type tag to a cryptographically random string. Engineers immediately recognize the object type in logs, and the alphabet (a-z,A-Z,0-9,_) is URL-safe without percent-encoding. - Compact URL-safe tokens (YouTube): Eleven-character Base64url strings such as
dQw4w9WgXcQcarry , keeping video links short while preventing users from enumerating adjacent videos. - Scoped or content-addressed IDs (GitHub): Repositories use human-readable slugs (
owner/repo), issues use per-repository auto-increment counters (#1, #2, #3), and commits use cryptographic content hashes.
The interactive script below demonstrates a prefixed random ID generator and compares entropy across different lengths and alphabets.
Custom ID Generator
Build your own prefixed ID system - experiment with different prefixes, lengths, and character sets
Key idea. Snowflake packs a 41-bit millisecond timestamp, a 10-bit machine ID (1,024 nodes), and a 12-bit per-millisecond sequence (4,096 IDs/ms) into a 64-bit integer, giving time-sortable, B-tree-friendly keys with only startup coordination and clock-skew protection. UUID v4 removes all coordination and clock dependencies at the cost of 16-byte size and random B-tree page splits. ULID and UUID v7 keep 128-bit coordination-free generation while restoring time-ordered writes.
Further reading
- Announcing Snowflake — Twitter Engineering Blog (2010) — the original 64-bit timestamp, worker, and sequence layout.
- RFC 9562: Universally Unique IDentifiers (UUIDs) — the specification defining random UUID v4 and time-ordered UUID v7.
- ULID Specification — 48-bit timestamp plus 80-bit random Crockford Base32 encoding.