How to Scale a System
Each scaling technique removes one bottleneck, and the order to apply them follows from where the load sits. A system with many repeated reads needs a cache before it splits its data across machines. A system facing a flood of writes needs a queue or a data split, because a cache does not help it. This lesson covers these techniques in roughly the order a growing system needs them, explaining what each one fixes and what it costs.
Vertical Scaling
Vertical scaling replaces a machine with a larger one that has more CPU cores, more memory, and faster disks, without changing the code. Because a larger cloud instance is available in minutes, vertical scaling is often the cheapest first step.
This approach has two limits: the largest available machine sets a ceiling, and one machine remains one point of failure. If that machine stops, the system stops.
Horizontal Scaling
Horizontal scaling adds more machines of the same size and spreads requests across them. A load balancer receives each request and forwards it to one of the servers.
This works only if the servers are stateless. If a server keeps a user's session in memory, that user's next request must reach the same server. If the session lives in a shared store instead, any server can handle any request, and a failed server is not a problem. The Load Balancer lesson explains this routing in detail.
Grasping the building blocks ("the lego pieces")
This part of the guide will focus on the various components that are often used to construct a system (the building blocks), and the design templates that provide a framework for structuring these blocks.
Core Building blocks
At the bare minimum you should know the core building blocks of system design
- Scaling stateless services with load balancing
- Scaling database reads with replication and caching
- Scaling database writes with partition (aka sharding)
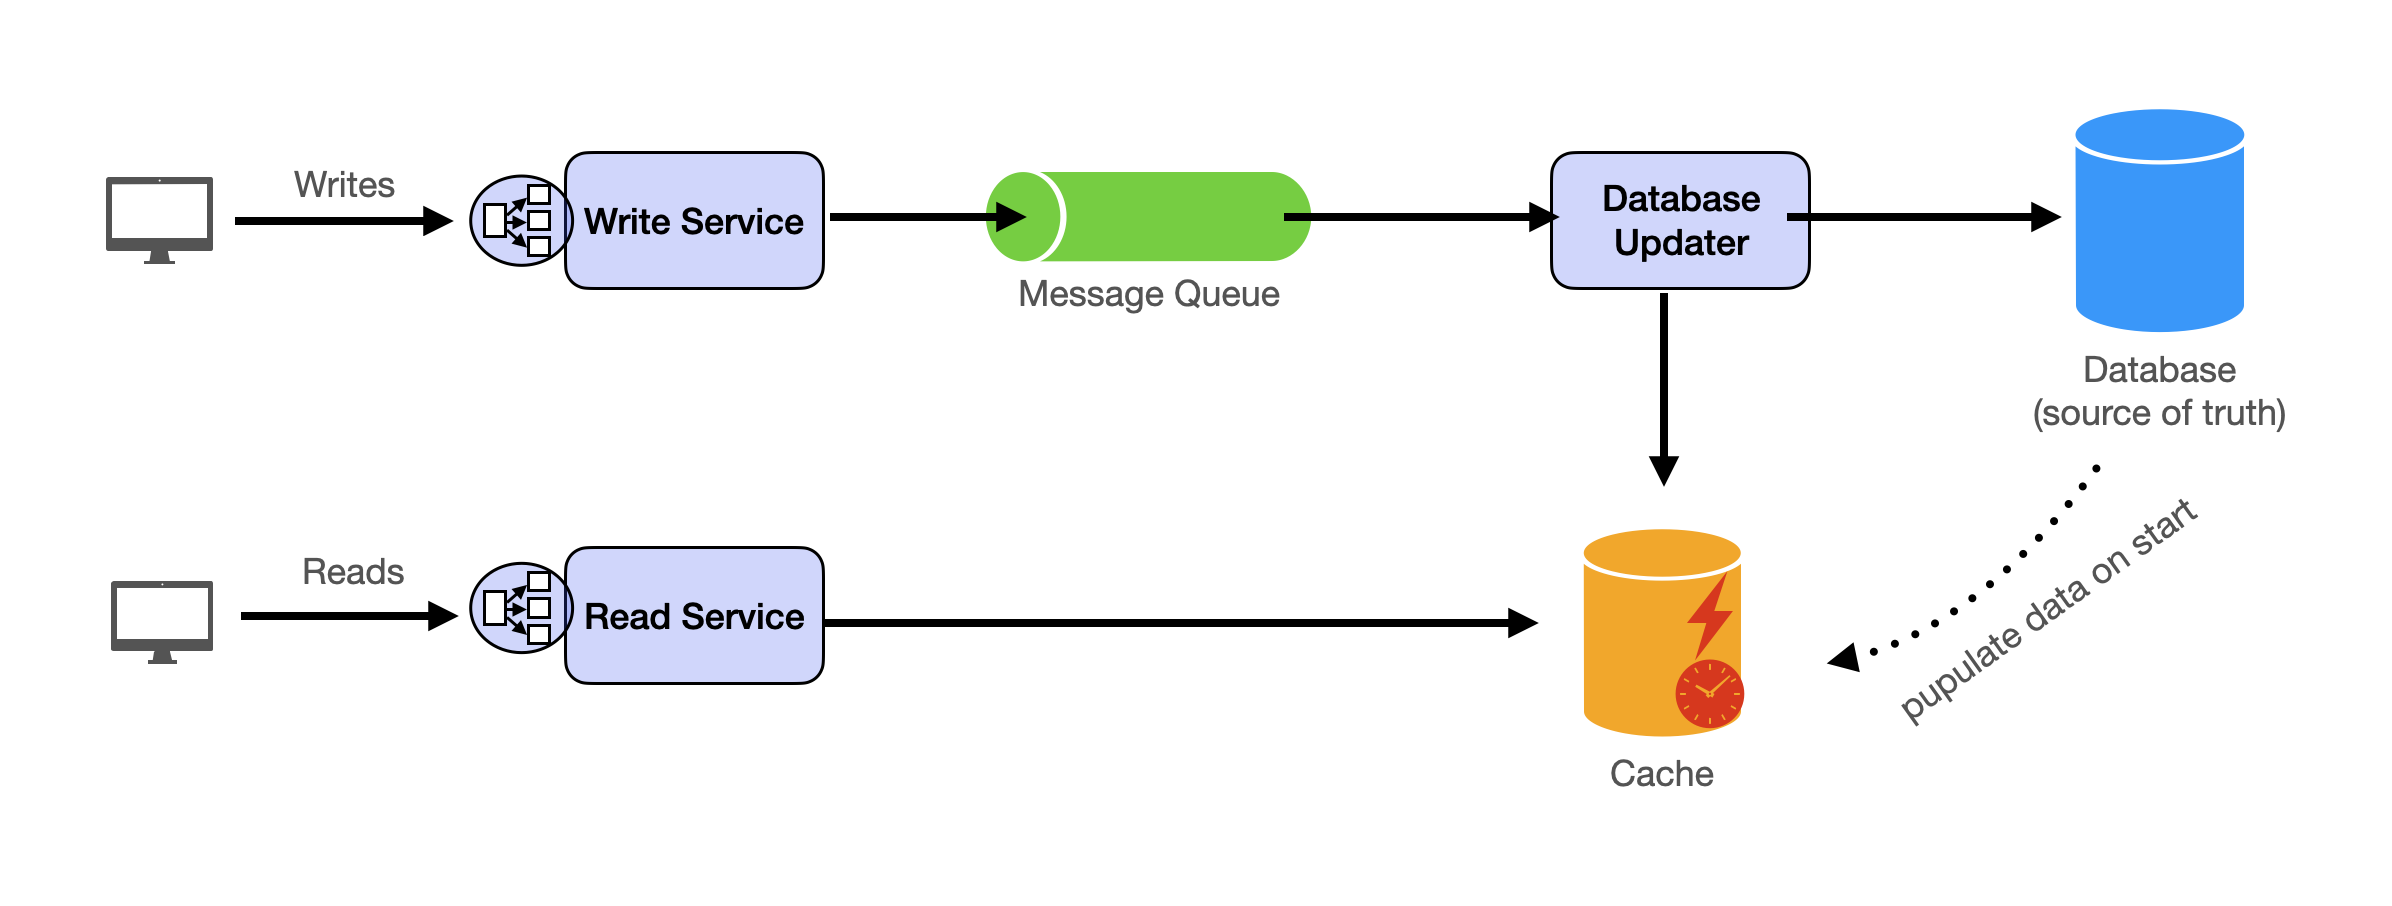
- Scaling data flow with message queues
System Design Template
With these building blocks, you will be able to apply our template to solve many system design problems. We will dive into the details in the Design Template section. Here’s a sneak peak:

Additional Building Blocks
Additionally, you will want to understand these concepts
- Processing large amount of data (aka “big data”) with batch and stream processing
- Particularly useful for solving data-intensive problems such as designing an analytics app
- Achieving consistency across services using distribution transaction or event sourcing
- Particularly useful for solving problems that require strict transactions such as designing financial apps
- Full text search: full-text index
- Storing data for the long term: data warehousing
On top of these, there are ad hoc knowledge you would want to know tailored to certain problems. For example, geohashing for designing location-based services like Yelp or Uber, operational transform to solve problems like designing Google Doc. You can learn these these on a case-by-case basis. System design interviews are supposed to test your general design skills and not specific knowledge.
Working through problems and building solutions using the building blocks
Finally, we have a series of practical problems for you to work through. You can find the problem in /problems. This hands-on practice will not only help you apply the principles learned but will also enhance your understanding of how to use the building blocks to construct effective solutions. The list of questions grow. We are actively adding more questions to the list.